We give AI agents sensors, hands, and the rules for using them.
Tamoz is a physical AI agent for the equipment you already run. It watches your sensors, and when a machine does something unexpected, it works out what's likely happening, says how sure it is, and proposes a response from the actions your team has defined. When a fix keeps working, it drafts a new rule for your team to approve, and that problem no longer needs a model.
What Tamoz is built for
A cold room warms up overnight. Equipment starts drawing more power. A sensor stops reporting. An alarm can tell you a reading crossed a line, but not whether a door was left open, a machine is failing, or the sensor is wrong. Someone still has to work that out before deciding whether to wait, investigate, or act.
Tamoz is built to do that first pass. People decide which actions it can propose and which need their approval, and every outcome is recorded.
While the cold room stays steady, no model runs. When a sensor stops reporting, Tamoz treats that as missing evidence, not as normal, so it becomes less certain instead of guessing.
It's aimed at monitoring, alerts, investigation, and recommendations across equipment and processes. Savings such as lower energy use or less material waste haven't been measured in a real operation, and a pilot is how we'd find out.
What you can do with Tamoz
- Watch it live. See sensor values and connection health as they arrive.
- Decide what happens. Approve, hold, or stop commands. Tamoz can propose an action, but it has no direct path to equipment.
- Go back and check. Step through a session's readings, commands, and outcomes on a timeline, and replay the session exactly.
- Try it before it touches anything. Build a simulated plant from a component library, inject faults, and score the system against a sealed record of what really happened. A device can run as a simple simulated twin before the hardware exists, and later be compared with what the real board reported.
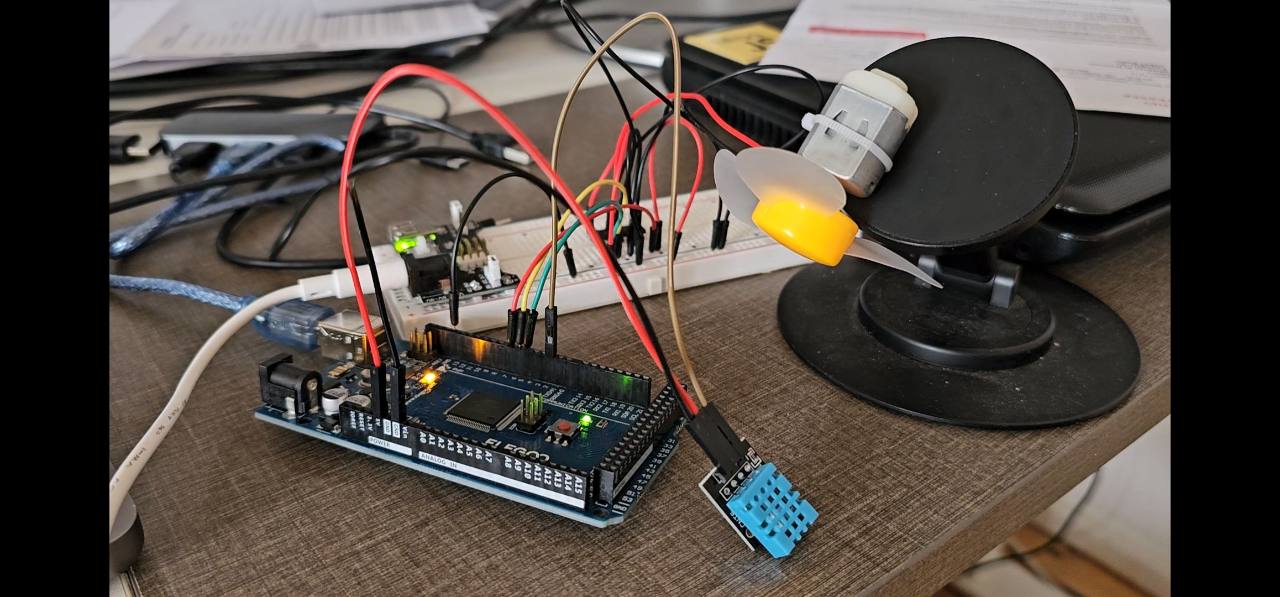
It has already run end to end on real hardware: Tamoz proposed an action, a person approved it, and the command reached a real board driving a fan. See how that went. In a simulated pump station with a real model, it also learned a new rule from verified repairs. Once approved, that rule handled five faults with no model call, all correct and on time. See the results.
Rules work. Who writes the next one?
Rules have run plants for decades, for good reason: they're fast, predictable, and easy to check. Tamoz keeps them. The hard part was never running a rule. It's knowing which rule to write, and keeping up as things change.
A rule only catches what someone understood when they wrote it. A new failure, a machine that has drifted from its neighbours, or a fault that looks like a different one falls through to whoever is on shift. Those are the cases Tamoz is for.
It works through the case no rule covers. When the same repair keeps working, it drafts a new rule with the evidence behind it. Once a person approves it, that rule handles the problem without calling a model. Here's how that went for one fault in our pump trial:
-
A pump starts to drift
Vibration climbs above this pump's own normal. No rule covers it yet.
-
So the model is asked
It explains what it sees, and how sure it is.
Saw: axial vibration about 34% above this pump's 24-hour baseline, while radial vibration and current stayed flat.
Thinks: shaft misalignment. Confidence 0.75.
Proposes: schedule maintenance for misalignment.
21 sfor the model to answer -
The repair works. Then it works again.
Each fault stayed away after the repair, so each one counts as verified.
- Pump 5: misalignment repaired, verified
- Pump 7: misalignment repaired, verified
- Pump 3: misalignment repaired, verified
- Three verified repairs. Enough to draft a rule.
-
The rule has to earn its place
When a pump's 15-minute axial vibration is at least 1.25 times its own 24-hour average
Do schedule alignment maintenance
- Replayed on past data: fired 3 times, agreed 3 times
- Approved (a scripted approver in this trial)
- Watched beside the model without acting: agreed 3 times
- Active
-
Five days later, the same fault
Same pump, same climb. This time the rule answers.
Decided by the rule. No model call.
2.74 is 1.33 times this pump's normal 2.05, above the rule's 1.25.
1.09 msto decide -
Same fault, before and after
First time: the model
Model calls1Time to decide21 sWarning to booking81 sAfter learning: the rule
Model calls0Time to decideabout 1 msWarning to booking60 sBoth waited the system's 60-second delay, and both booked the same repair. In this trial one of three fault types earned a rule.
It's an ordinary rule. Your team can read it, question it, and switch it off. If the equipment changes or the repair stops holding, it switches itself off and the model takes over. The aim is for the model's job to shrink to what's still unknown, while what you've learned stays in rules you own.
An agent that grades its own work learns to flatter itself, so Tamoz learns from outcomes, not from its own account of them. It can also suggest changes to how it works, but it can't approve them itself. Read how rules are learned.
How it's built
We call the whole system Tamoz, and it has three parts with separate jobs: one watches and acts, one reasons, and one gives people a plant to build and test, and a console to run it. The split is the point. The part that reasons can't touch equipment, and the part that touches equipment follows fixed rules.
- Agentic Stream watches and acts. It runs all the time, recording each reading with its timing and quality, and decides when something has changed enough to need reasoning. It also carries out every action, checking the proposal against policy again just before acting and recording what happened. Approved rules learned from earlier repairs run here, without a model.
- The Tamoz agent reasons. It works with any model. It gets one snapshot of the situation and a limit on how much reasoning it can spend, can read further evidence through read-only tools an operator has granted, and returns a proposal with its uncertainty. It can also draft a rule from verified repairs for a person to review. Its work is saved as it goes, so it can recover after a crash, and it has no direct path to equipment.
- Streams Simulator is the plant and the console. It can stand in for a plant or connect to real hardware. People use it to watch sensor values, approve or stop actions, and review what happened.
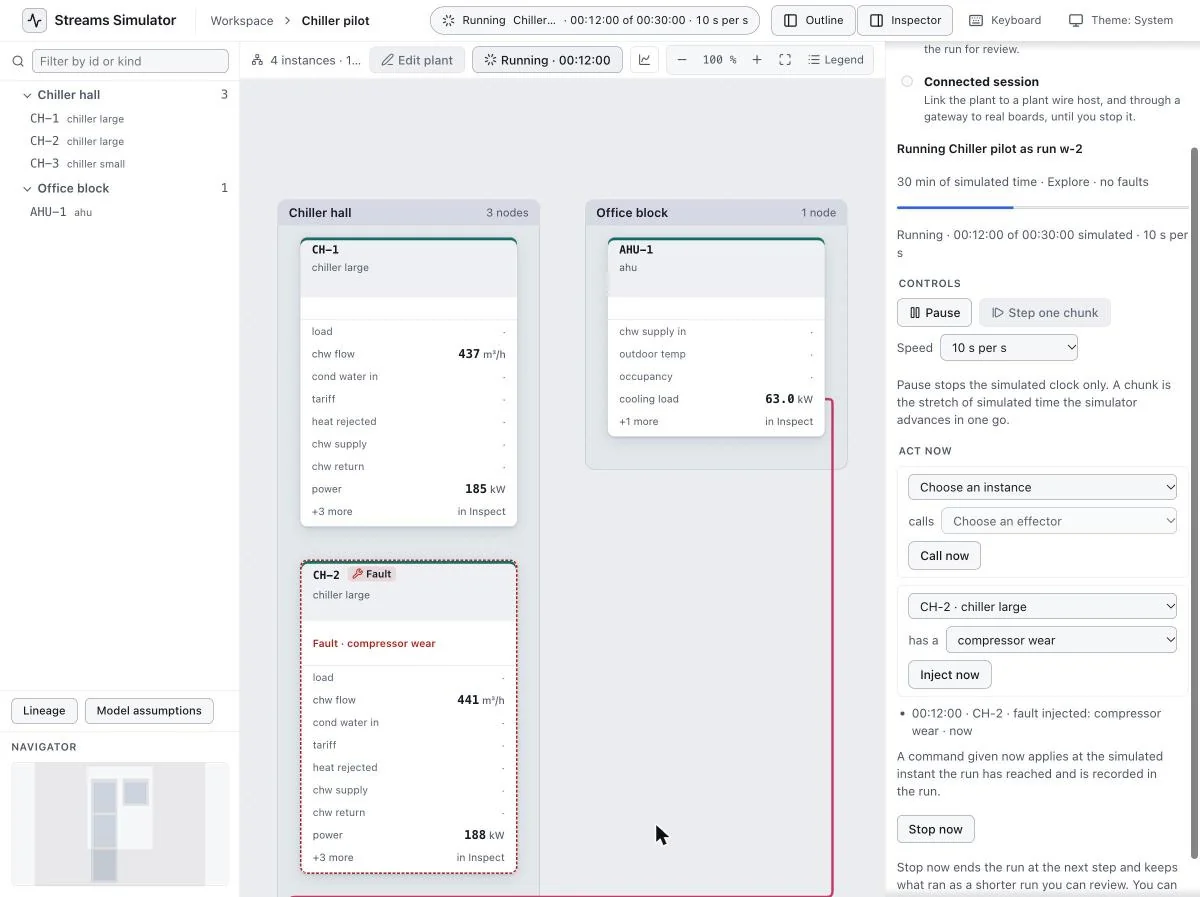
Together they form one loop, from readings to outcomes.
The system from readings to outcomes
Scroll sideways to see the whole loop.
How a decision works
It's 2 a.m. A cold room that should hold 4 °C reads 8 °C and is still warming. Here's how Tamoz would handle it, as an illustration.
- It freezes the evidence. The readings, their timing, and their quality become one fixed snapshot, so every later step can be traced back to the same facts.
- It goes and looks. A temperature alone can't explain this, so the agent checks what you've allowed it to read, such as the door sensor's log. If it still can't tell, it says so and names what's missing.
- It makes its case.
Saw: 8 °C and climbing for 40 minutes. Door open since 02:10.
Thinks: the door was left open. Fairly sure, but the compressor isn't ruled out.
Proposes: alert the night shift. - It gets checked again. Just before anything happens, policy confirms the situation hasn't moved on and whether a person has to approve. If the agent proposed cooling, it could choose a mode, but never the motor power or run time.
- It doesn't take "done" for an answer. The command being received, the device reporting success, and the room actually cooling are kept as three separate facts.
- It remembers. If the door closes and the room recovers, that outcome becomes evidence for next time.
What has been tested
| Test | Reasoning | Equipment | Main result |
|---|---|---|---|
| Pump station | Real model | Simulated | A learned rule did the model's job on one fault type |
| Bench | Real model | Real board and fan | The whole route ran, in three sessions |
| Earlier rounds | Scripted | Simulated | The machinery was exercised across five industries, with gaps listed |
It hasn't run in a real operation yet, so none of this establishes industrial performance or savings.
A pump station with a real model
One simulated station with eight pumps and 3 healthy look-alikes. Three fault types were each injected 6 times, 18 faults in all, and we ran the same test days twice, with the learned rule and without it. A fault counts below only if the right repair was booked before its deadline.
| Right repair booked on time | With the rule | Without it | Decided by, with the rule |
|---|---|---|---|
| Misalignment (6 faults) | 5 | 5 | The rule, no model call |
| Bearing wear (6 faults) | 2 | 1 | The model |
| Sensor drift (6 faults) | 0 | 0 | The model |
| All faults (18) | 7 | 6 |
Faults detected: 17 and 15 of 18. Correct diagnosis: 11 of 18 both ways. Action on a healthy look-alike: 0 of 3 both ways.
What this shows. Where a rule existed, it did the model's job with no model call: five misalignments, all correct and on time. So the gain is fewer model calls, not more repairs. The small differences in the other rows are the model's own variation. So far, one of three fault types has earned a rule, and the model handled the rest. In this trial the approver was scripted. Read the full trial.
A pilot would measure these same numbers on your equipment.
From Tamoz to a real board
We have run the whole route on real hardware: from Tamoz's proposal, through policy and a person's approval, to a command on a small board with a fan motor. Three recorded sessions on 25 October 2026 took this path.
This was a bench test, not plant equipment. A team member approved each command, the thresholds were set for the bench, and confirmation came from the board's own report. With the motor disconnected, the board still reported success, so these sessions don't measure a physical effect such as cooling. That's one reason a pilot starts with monitoring and recommendations, and why any later equipment action would need an independent check, such as a temperature or current reading. Read the bench evidence or the earlier motor test.
Simulator rounds across several industries
Earlier rounds exercised timing, approvals, memory, and recovery in aquaculture, water networks, greenhouses, cold chain, and logistics. Their reasoning was scripted, so they tested the machinery around the model, not its ability to diagnose. Read the simulator evidence.
Where it stands
Tamoz is pre-release software, tested in simulation and on a small bench. It hasn't been deployed in the field yet. It isn't a certified safety system, so yours stay responsible for protection.
What a first pilot would answer
Simulation and a bench can't tell you what only your plant can:
- Does it find and explain real problems sooner than your alarms and your team do today?
- Which recurring problems can become rules your team trusts?
- What does that save in energy, material, or time spent on alerts?
It starts small and read-only: one problem your team wants to solve, and a result you can measure. Your team decides what to do, and any equipment action comes later under a separate agreement.
You'd work directly with our founding team of three, who can use your existing data or install suitable sensors. You'd come away with recorded findings, recommendations with their evidence, and a review of what worked and what needs more investigation.